AI Agent Evaluation: How to Measure What Your AI Agents Actually Do
Key takeaways:
- AI agent evaluation measures the complete workflow not just the final response including task outcomes, execution paths, tool usage, memory, cost, and safety.
- Task Success Rate is an important top-level metric, but teams should also evaluate trajectory quality, tool accuracy, context retention, efficiency, and policy compliance.
- A strong evaluation process combines clear success criteria, representative test scenarios, complete agent traces, component-level testing, and repeated regression tests.
- Production-ready evaluation should use a mix of deterministic checks, LLM-as-a-judge scoring, and human review depending on the type and risk of the task.
- AI agent evaluation should be continuous: test before deployment, monitor real-world performance, turn production failures into new test cases, and rerun regression tests after system changes.
AI agents do more than generate responses. They plan tasks, retrieve information, call tools, interact with business systems, and complete actions across workflows.
This makes AI agent evaluation different from traditional model testing. Teams need to evaluate the final outcome, execution path, tool behavior, memory, cost, and safety together.
A strong evaluation process helps identify where an agent fails before those failures affect production workflows. It also gives teams measurable criteria for comparing prompts, models, tools, and orchestration changes.
What Is AI Agent Evaluation?
AI agent evaluation is the process of measuring how reliably an agent completes its assigned tasks. It evaluates the complete execution flow instead of checking only the final response.
An AI agent usually performs several actions during one request.
These actions can include:
- Understanding user intent
- Planning the next step
- Retrieving relevant information
- Selecting external tools
- Passing tool parameters
- Updating connected systems
- Returning the final response
Each action can introduce a different failure point.
For example, a customer support agent may tell a user that an order was cancelled. The response can look correct even when the cancellation API failed or the wrong order ID was submitted.
AI agent performance therefore depends on more than language quality. Teams must verify whether the expected business outcome actually occurred.
Traditional AI model testing remains important for measuring model-level behavior. Agent evaluation extends that process across orchestration, tools, memory, retrieval, and system execution.
AI Agent Evaluation vs. LLM Evaluation
LLM evaluation and AI agent evaluation measure different layers of an AI system. LLM evaluation focuses mainly on model outputs, while agent evaluation focuses on complete task execution.
The main differences include:
| LLM Evaluation |
AI Agent Evaluation |
| Measures individual responses |
Measures complete workflows |
| Focuses on output quality |
Focuses on task outcomes |
| Usually tests prompt-response pairs |
Tests multi-step execution |
| Measures relevance and accuracy |
Measures tools, trajectories, cost, and safety |
| Has limited external interaction |
Connects with APIs and business systems |
| Can evaluate one response |
Often requires repeated task runs |
A strong language model does not automatically create a reliable agent.
Agent performance also depends on routing logic, prompts, retrieval systems, memory, APIs, and execution rules. A failure in any one of these components can cause the complete workflow to fail.
Organizations comparing AI agents, chatbots, and LLM applications should therefore evaluate the complete architecture instead of measuring the underlying model alone.
Build AI Agents You Can Measure and Trust
Prismetric helps design and evaluate AI agents across task success, tool usage, execution paths, memory, safety, latency, and cost.
Evaluate Your AI Agent
Core AI Agent Evaluation Metrics
AI agent evaluation metrics should measure both task completion and execution quality. Task Success Rate provides a useful top-level result, but it does not explain how the agent reached that result.
Most evaluation frameworks track six areas:
| Evaluation Area |
What Teams Measure |
| Task completion |
Successful and failed task outcomes |
| Trajectory quality |
Steps, retries, loops, and unnecessary actions |
| Tool usage |
Tool selection, arguments, and execution |
| Context and memory |
Information retention and retrieval quality |
| Efficiency |
Latency, token usage, and cost |
| Safety |
Permissions, policies, and escalation behavior |
Task Completion
Task Success Rate measures how often an agent achieves the required outcome. The metric should verify the real system state wherever possible.
A completed-looking response is not enough. The underlying action must also succeed.
Trajectory and Tool Usage
Trajectory evaluation examines the sequence of actions taken during execution. Teams look for unnecessary loops, repeated calls, missing steps, and incorrect decisions.
Multiple trajectories can still be valid. Evaluation should enforce required workflow conditions without rejecting every alternative execution path.
Tool evaluation focuses on whether the agent selected the correct function and passed accurate parameters. Systems connected through AI integration services may need additional checks for IDs, schemas, permissions, and API responses.
Context, Cost, and Safety
Long-running and multi-turn agents must retain important information across interactions. Memory failures can cause repeated questions, incorrect actions, or loss of workflow state.
Teams should also monitor execution time, token consumption, retries, and cost per successful task. Enterprise deployments need these metrics to determine whether an agent can operate reliably at scale.
Organizations building enterprise AI systems usually define these requirements before production deployment.
Planning an agent that needs reliable evaluation from the start?
Explore Prismetric’s AI agent development services for architecture, integration, and production deployment support.
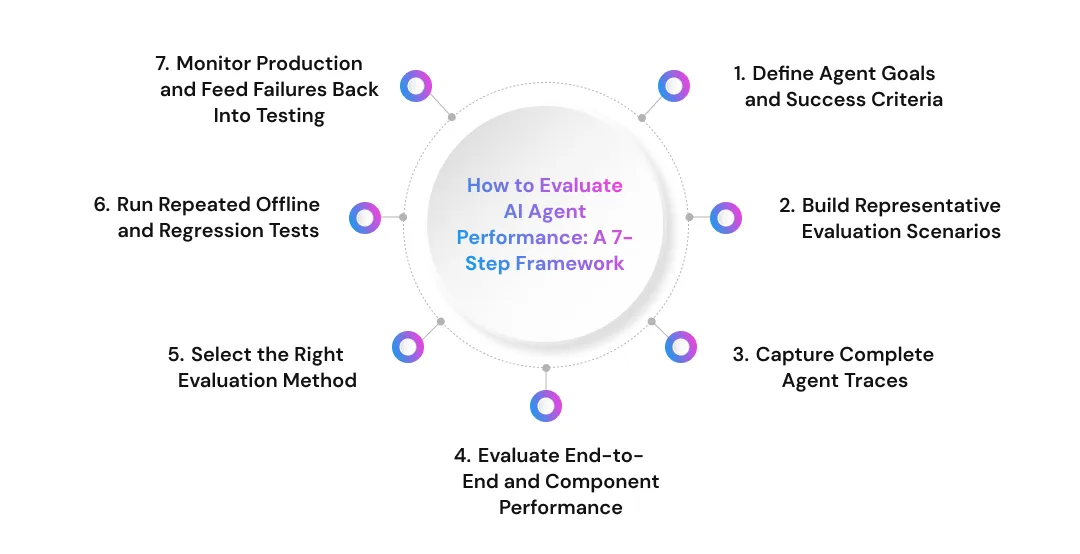
How to Evaluate AI Agent Performance: A 7-Step Framework
AI agent performance cannot be measured through one test or metric. Teams need a structured process that checks outcomes, execution paths, tools, and production behavior together.
A practical evaluation framework usually starts before deployment and continues after the agent reaches real users.
Step 1: Define Agent Goals and Success Criteria
Every evaluation starts with a clear task objective. Teams need to define what the agent must achieve and which conditions determine success or failure.
Success criteria should cover:
- Expected task outcome
- Required workflow steps
- Allowed actions
- Restricted actions
- Escalation conditions
- Completion requirements
For example, an order cancellation agent should verify the order, confirm eligibility, process the cancellation, and return the correct status. The task should fail if the agent only generates a cancellation message without changing the order state.
Teams implementing AI workflow automation should define these requirements before building evaluation cases.
Step 2: Build Representative Evaluation Scenarios
Evaluation datasets should reflect the conditions an agent will face during actual use. Testing only normal requests creates an incomplete view of AI agent performance.
Most teams include scenarios such as:
- Routine user requests
- Ambiguous instructions
- Missing information
- Multi-turn conversations
- Tool failures
- Invalid inputs
- Restricted actions
- Previously observed failures
Teams can define a golden outcome when the correct result is deterministic. Tasks with several acceptable answers can instead use scoring criteria or evaluation rubrics.
An AI workflow discovery checklist can also help identify important workflow conditions before teams create evaluation datasets.
Step 3: Capture Complete Agent Traces
Agent traces show what happens between the user request and the final result. They provide the execution history needed to understand why an agent succeeded or failed.
A complete trace can capture:
- User inputs
- Retrieved context
- Tool selections
- Tool parameters
- API responses
- Retries
- Errors
- Final outputs
A failed task may come from the model, retrieval layer, tool call, or connected system. Trace-level evaluation helps teams locate that failure instead of treating the complete agent as one black box.
Organizations integrating LLMs into applications need this visibility because model behavior and software failures often appear inside the same workflow.
Step 4: Evaluate End-to-End and Component Performance
End-to-end evaluation measures whether the complete task succeeded. Component-level evaluation measures the individual systems responsible for producing that outcome.
Teams commonly evaluate:
- Routing
- Retrieval
- Tool selection
- Tool arguments
- Memory
- Agent handoffs
- Response generation
This separation improves debugging. A successful model response can still exist inside a failed workflow, while one weak component can reduce the reliability of the complete agent.
Step 5: Select the Right Evaluation Method
Different agent behaviors require different evaluation methods. Most production evaluation systems combine deterministic checks, model-based scoring, and human review.
Deterministic checks work well for structured conditions. They can verify database changes, schema compliance, permissions, numerical values, or required tool calls.
LLM-as-a-judge works better for qualitative criteria. A judge model can score relevance, completeness, instruction adherence, and semantic correctness where exact matching is too restrictive.
Human evaluation supports ambiguous, sensitive, and high-risk cases. Teams also use human-reviewed examples to verify whether automated judges are scoring consistently.
Organizations refining agent prompts and judge instructions may use prompt engineering expertise to create clearer execution rules and evaluation rubrics.
Step 6: Run Repeated Offline and Regression Tests
AI agents can produce different execution paths for the same request. One successful run does not prove that the workflow is reliable.
Teams should run important scenarios multiple times and compare results across:
- Model versions
- Prompt changes
- Tool configurations
- Retrieval settings
- Orchestration logic
A regression suite stores important scenarios and reruns them after system changes. This helps teams detect when an improvement in one workflow creates a new failure somewhere else.
Security scenarios should also be included. Agents that process external content should be tested against prompt injection, unauthorized requests, and attempts to bypass tool restrictions.
Step 7: Monitor Production and Feed Failures Back Into Testing
Production evaluation shows how agents behave with real users, real tools, and changing business systems. These conditions often expose problems that controlled datasets do not contain.
Teams should monitor metrics such as:
- Task success
- Tool errors
- Latency
- Token consumption
- Retry frequency
- User feedback
- Policy violations
Important production failures should become new regression cases. The evaluation dataset therefore grows as the agent encounters new conditions.
The process becomes continuous:
Test before deployment → monitor production → capture failures → add evaluation cases → rerun regression tests
Organizations using AI implementation services can incorporate this cycle into deployment, monitoring, and ongoing agent optimization.
Move From a Working Demo to a Reliable AI Agent
Test real workflows, tool calls, edge cases, permissions, and failure scenarios before your AI agent reaches production.
Build a Production-Ready Agent
Offline vs. Online AI Agent Evaluation
Offline and online evaluation measure AI agent performance in different environments. Most production teams use both because controlled tests cannot represent every real-world condition.
Offline evaluation is useful for:
- Development testing
- Regression testing
- Prompt comparisons
- Model comparisons
- Security scenarios
- Tool failure simulations
Offline tests give teams repeatable conditions. They make it easier to compare system changes before those changes reach production.
Online evaluation measures how the agent behaves with real users and connected systems.
Teams typically monitor:
- Task success
- Tool failures
- Response latency
- Token consumption
- User feedback
- Policy violations
Production traces often reveal scenarios that development datasets missed. Teams can convert these failures into new offline tests for future releases.
Agents using retrieval-augmented generation should also evaluate retrieval quality during both stages. The system must retrieve relevant information and use that information correctly during execution.
Organizations using RAG as a service can evaluate retrieval separately while still measuring the final task outcome.
Practical AI Agent Evaluation Example
Consider a customer support agent responsible for cancelling eligible orders. The user asks the agent to cancel an order and confirm the result.
The evaluation should not stop when the agent produces a confirmation message.
Teams should verify:
- The correct order was identified
- Cancellation eligibility was checked
- The correct tool was selected
- The correct order ID was submitted
- The order status actually changed
- The customer received the correct response
Trajectory evaluation should also check whether the agent followed mandatory workflow rules. Alternative execution paths can still pass when they produce the correct result without violating required conditions.
If the system uses Model Context Protocol, teams should also verify tool access, parameters, and permission boundaries.
The same evaluation structure applies across different agentic AI use cases. The business outcome changes, but task success, tool behavior, and execution quality remain important.
Build AI Agents That Perform Reliably in Real Workflows
Prismetric develops enterprise AI agents with secure integrations, workflow orchestration, RAG, memory, evaluation, and continuous performance monitoring.
Talk to Our AI Agent Experts
How Prismetric Builds and Evaluates Enterprise AI Agent Systems
As an AI agent development company, Prismetric builds enterprise AI agents around real business workflows, data sources, tools, and operational requirements. Its AI agent services cover strategy, custom development, system integration, deployment, and ongoing optimization.
Enterprise agents need more than a capable language model. They require reliable tool execution, workflow orchestration, memory, system integrations, security controls, and continuous performance monitoring.
Prismetric develops AI agent systems using technologies and architectures such as:
- AutoGen Studio
- CrewAI
- Vertex AI Agent Builder
- Retrieval-Augmented Generation systems
- Private and enterprise LLM deployments
- Multi-agent systems with memory and orchestration
These capabilities support agents that can retrieve enterprise information, use external tools, coordinate multi-step tasks, and operate across connected business systems.
Our teams work across AI use cases such as:
- Customer support automation
- Internal business operations
- Research and data analysis
- Workflow management
- Enterprise copilots
- API-connected task automation
Prismetric reports 1,000+ clients, 1,500+ solutions developed, operations across 50+ countries, and a team of 100+ developers.
| Enterprise AI Capability |
Prismetric Delivery Focus |
| AI Agent Development |
Custom agents for business workflows |
| System Integration |
CRM, ERP, databases, APIs, and internal platforms |
| RAG Development |
Business-specific retrieval and knowledge systems |
| Multi-Agent Systems |
Coordinated agents for multi-step operations |
| AI Testing |
Functional, performance, and user acceptance testing |
| Production Support |
Monitoring, maintenance, and continuous optimization |
We help enterprises build:
- Workflow automation agents
- Enterprise AI copilots
- RAG-enabled agent systems
- Multi-agent orchestration architectures
- Secure API-connected AI workflows
Our engineering approach focuses on production requirements such as:
- Workflow reliability
- Tool and API integration
- Security and compliance
- Performance monitoring
- Scalable deployment
- Ongoing optimization
Prismetric supports AI projects from strategy and feasibility assessment through deployment and post-launch monitoring, helping organizations move beyond isolated AI experiments toward production systems integrated with everyday operations.
Planning to build an agent that can perform reliably across real enterprise workflows?
Explore Prismetric’s AI agent development services to move from use-case definition to production deployment.
Common AI Agent Evaluation Mistakes
AI agent evaluation becomes less reliable when teams test only the most visible part of the workflow.
Common mistakes include:
- Evaluating only the final response
- Testing each scenario only once
- Requiring one exact trajectory
- Relying only on generic benchmarks
- Using an uncalibrated LLM judge
- Ignoring production failures
A correct response can hide an incorrect tool call. A successful test can also hide inconsistent behavior across repeated runs.
Generic benchmarks help compare models, but they may not represent actual business workflows. Product-specific evaluation cases should reflect real tools, permissions, users, and failure conditions.
Teams should also include security and governance criteria where agents can perform consequential actions. Relevant AI regulation and compliance requirements can influence which actions require logging, review, or human approval.
Teams designing evaluation checkpoints early can also review how to build an AI agent before production implementation.
Frequently Asked Questions About AI Agent Development Cost
AI agent development can range from a few thousand dollars for a focused single-task agent to $250,000+ for complex enterprise and multi-agent systems. The final price depends heavily on integrations, autonomy, data requirements, security, testing, and deployment needs.
A simple agent normally handles one defined workflow with limited integrations. A medium-complexity agent may use multiple tools, RAG, memory, APIs, and multi-step decision-making.
Complex agents add capabilities such as multi-agent coordination, advanced permissions, enterprise integrations, evaluation systems, compliance controls, and high-volume production infrastructure.
Simple AI agents generally sit at the lower end of the development budget because they have a narrow scope and fewer external dependencies.
Typical examples include:
- FAQ and knowledge agents
- Basic lead qualification agents
- Internal information assistants
- Single-workflow automation agents
Complexity increases the amount of engineering, integration, testing, monitoring, and exception handling required to make an agent reliable in production.
Costs usually rise when the agent needs:
- Multiple APIs or business-system integrations
- Long-term memory or RAG
- Complex decision logic
- Several cooperating agents
- Security and permission controls
- Human approval workflows
Enterprise-grade agents can reach tens or hundreds of thousands of dollars when they coordinate multiple workflows, systems, users, and agents. Published 2026 estimates commonly place sophisticated multi-agent and enterprise implementations well above simpler production agents.
The development fee is only one part of that budget.
Organizations may also need to account for monitoring, evaluation, infrastructure, security, integrations, maintenance, and ongoing model usage.
The number of features alone does not determine the budget. The biggest cost drivers are usually the amount of custom engineering and the reliability required from the finished system.
Important factors include:
- Number and complexity of workflows
- Third-party integrations
- LLM and model requirements
- RAG and enterprise data connections
- Memory requirements
- Multi-agent orchestration
- Security and compliance
- Testing and evaluation
- Expected user and task volume
Not always. Development quotes usually cover designing and building the agent, while LLM API usage, cloud infrastructure, vector databases, monitoring tools, and other services may be billed separately.
Businesses should therefore ask for both the one-time development cost and the expected monthly operating cost before approving a project.
Monthly cost depends on how frequently the agent operates, which models it uses, how many tokens it consumes, and which external services it calls. Production systems can also incur costs for hosting, databases, observability, evaluation, and support.
High-volume agents may cost considerably more to operate than low-traffic internal assistants.
Retries and unnecessarily long agent workflows can increase that expense further.
Yes. RAG usually adds work around document ingestion, embeddings, retrieval, vector storage, access controls, data updates, and evaluation.
The additional investment can be worthwhile when an agent needs to answer or act using private, frequently changing, or business-specific information.
Usually, yes. A multi-agent architecture introduces additional orchestration, communication, state management, failure handling, testing, and monitoring requirements.
Teams may need to evaluate:
- How tasks are assigned between agents
- How agents share context
- When handoffs occur
- How conflicting decisions are resolved
- What happens when one agent fails
Buying is often cheaper when the workflow is standard and an existing product already meets most requirements. Custom development becomes more attractive when the workflow is proprietary, requires deep system integration, or creates strategic business value.
A company should compare total ownership cost rather than only the initial subscription or development price.
That comparison should include customization, integration, recurring fees, maintenance, data control, and switching costs.
A narrowly scoped agent or proof of concept may be developed within a few weeks, while integrated production systems can require several weeks or months. Current 2026 pricing guides also show development timelines increasing substantially as integrations and agent complexity grow.
Enterprise deployments may take longer because testing, security, approvals, and integration work become part of the project.
The initial build price does not always represent the complete cost of ownership.
Businesses should budget for:
- LLM and API consumption
- Cloud infrastructure
- Vector databases and RAG services
- Monitoring and observability
- Evaluation and regression testing
- Data updates
- Maintenance and bug fixes
- Security and compliance
- Future integration changes
Yes. Start with one valuable workflow instead of building a large autonomous system immediately. A smaller production-ready agent provides real usage data before additional complexity is added.
You can also control cost by:
- Reusing existing APIs and infrastructure
- Limiting unnecessary integrations
- Routing simpler tasks to lower-cost models
- Defining clear success criteria early
- Testing a focused MVP before expanding
- Monitoring token and tool usage after launch
For many businesses, yes. An MVP helps validate whether the workflow, integrations, and expected business value justify a larger investment.
It can answer important questions early:
- Can the agent complete the workflow reliably?
- Which integrations are actually necessary?
- How much does each successful task cost?
- Where does human review remain necessary?
- Is the expected ROI strong enough to scale?
Compare the agent’s total cost with measurable outcomes such as employee hours saved, faster processing, increased conversions, lower support costs, or additional workflow capacity.
The more useful metric is often cost per successfully completed business task, rather than token cost or development cost alone.